
All in One View
Content from Working with files and directories
Last updated on 2026-10-21 | Edit this page
Estimated time: 25 minutes
Overview
Questions
- How can I create, copy, move, and delete files and directories?
- How can I read files?
Objectives
- apply file naming conventions under guidance when creating a project directory
- apply shell commands to create, view, rename, copy and delete files and directories
- apply tab completion, the command history and wildcards to save typing
Working with files and folders
As well as navigating directories, we can interact with files on the command line: we can create them, read them, rename them and delete them. In fact, there’s really no limit to what we can do in the shell, but even experienced shell users still switch to graphical user interfaces (GUIs) for many tasks, such as editing formatted text documents, browsing the web or editing images. But if we wanted to make the same change to hundreds of files, say, rename all the images of a scanned book, then we could automate that work by using shell commands.
Creating a project directory
Let’s create a directory for the project we will work on for the rest of this workshop. First, we move to the Desktop, so that we can easily find the directory in the graphical file manager, too:
OUTPUT
/Users/riley/DesktopWhere is my Desktop?
On some Windows computers, the Desktop is inside a OneDrive folder,
for example OneDrive/Desktop. If cd Desktop
doesn’t work, ask your instructor for help.
Here, we create a new directory with the mkdir command
(meaning ‘make directories’). We call it my-git-repo-
followed by our first name in lower case letters, for example
my-git-repo-riley. Please use your own name instead of
<name> in the commands of this lesson:
OUTPUT
my-git-repo-rileyWhy add your name?
Later in the workshop, this directory will become a repository on Codeberg, next to the repositories of all other participants, and you will work with the repository of a partner. If everybody’s repository had the same name, it would be easy to mix them up. With your name in it, it’s always clear whose repository you are looking at.
Now let’s move into the new directory. But wait! There’s a trick to
make things a bit quicker. Instead of typing the whole name, type
cd my and then press the Tab key. We notice that
the shell completes the line to cd my-git-repo-riley/.
Press Enter to run the command.
OUTPUT
/Users/riley/Desktop/my-git-repo-rileyTab for Auto-complete
Pressing tab at any time within the shell will prompt it to attempt to auto-complete the line based on the files or sub-directories in the current directory. Where two or more files have the same characters, the auto-complete will only fill up to the first point of difference, after which we can add more characters, and try using tab again. We would encourage using this method throughout today to see how it behaves (as it saves loads of time and effort!).
Creating and reading files
Our directory is still empty. Every project should have a
README.md file that explains what the project is about, so
let’s create one. To create a new, empty file, we can use the
touch command:
OUTPUT
README.mdThe .md extension signifies that we have chosen to use
the Markdown format, a lightweight markup language with plain text
formatting syntax. We will see more of Markdown later.
To write something into a file, we would usually use a text editor,
which we will meet in the Git episodes. For a quick start, we can also
use the echo command, which prints a text, together with
>, which sends the output of a command into a file
instead of to the screen:
The hash character # at the beginning of the line makes
it a heading in Markdown.
> overwrites files
If the file after > already exists, its content is
replaced without warning. Use >> instead to add a
line at the end of a file.
To look at the content of the file, we use the cat
command:
OUTPUT
# My Git repositoryRe-using commands
On a blank command prompt, press the up arrow key and notice that the previous command you typed appears before your cursor. We can continue pressing the up arrow to cycle through your previous commands. The down arrow cycles back toward your most recent command. This is another important labour-saving function and something we’ll use a lot.
Adding a line
Use the up arrow key to get back the echo command, and
change it so that it adds the line “This is where I practise
Git.” to README.md. Then check the content of the file.
cat prints the whole file to the screen. For long files,
this is not very practical, so there are a few more commands to view
files. Try them with README.md:
-
head README.mdshows the first ten lines of a file (head -n 1 README.mdonly the first line), -
tail README.mdshows the last ten lines (tail -n 1 README.mdonly the last line), -
less README.mdshows the file one screen at a time: use the spacebar to go to the next screen and q to quit.
Remember how to quit less with q: Git uses
less to show long output, for example the history of a
project with git log.
Moving, copying and deleting files
Instead of moving a file, you might want to copy a
file (make a duplicate), for instance to make a backup before modifying
a file. The cp command takes two arguments: the old name
and the new name.
OUTPUT
README-backup.md README.mdWe may also want to change a file name to something more descriptive.
We can move it to a new name by using the
mv or move command, giving it the old name as the first
argument and the new name as the second argument:
OUTPUT
README.md old-readme.mdThis is equivalent to the ‘rename file’ function.
Moving a file into a directory
If the last argument you give to the mv command is a
directory, not a file, the file given in the first argument will be
moved to that directory. Create a directory called backup
and use the mv command to move the file
old-readme.md into it. Check the result with
ls and ls backup.
If we had lots of files, it would be tedious to type all the
filenames. Luckily the shell supports wildcards! The ?
matches exactly one character and * matches zero or more
characters. For example, ls backup/*.md lists all files in
the backup directory whose names end in
.md.
More on wildcards
Wildcards are a feature of the shell and will therefore work with
any command. The shell will expand wildcards to a list of files
and/or directories before the command is executed, and the command will
never see the wildcards. As an exception, if a wildcard expression does
not match any file, Bash will pass the expression as a parameter to the
command as it is. For example typing ls *.pdf results in an
error message that there is no file called *.pdf.
Finally, onto deleting. The command to delete a file is
rm, or remove. Adding the -r flag, we can
delete directories with all their content.
Unlike deleting from within our graphical user interface,
there is no warning, no recycling bin from which you
can get the files back and no other undo options! For that
reason, please be very careful with rm and extremely
careful with rm -r.
Let’s clean up and delete the backup, so that only our
README.md is left before we start with Git:
OUTPUT
README.mdVersion control as a safety net
Git cannot protect you from rm either, but it can help a
lot: if a file is part of a Git repository and its changes are
committed, you can get the last committed version back even after
deleting it. This is one of many reasons to use version control, as we
will see next.
-
mkdircreates a directory andtouchcreates an empty file -
echo "text" > filewrites text into a file,>>adds it at the end -
cat,head,tailandlessshow the content of files -
mvmoves or renames,cpcopies andrmdeletes files – there is no undo forrm - Tab completion, the up arrow key and wildcards (
*,?) save a lot of typing
Content from What is Git/Codeberg?
Last updated on 2026-10-21 | Edit this page
Estimated time: 10 minutes
Overview
Questions
- What is Git?
- What is Codeberg?
Objectives
- explain the relevance and benefits of version control
- explain Git as an example of distributed versioning software and how it differs from a hosting platform like Codeberg
What is Version Control?
Version control is a name used for software which can help you record changes you make to the files in a directory on your computer. Version control software and tools (such as Git and Subversion/SVN) are often associated with software development, and increasingly, they are being used to collaborate in research and academic environments. Version control systems work best with plain text files such as documents or computer code, but modern version control systems can be used to track changes in most types of file.
At its most basic level, version control software helps us register and track sets of changes made to files on our computer. We can then reason about and share those changes with others. As we build up sets of changes over time, we begin to see some benefits.
Benefits of using version control?
- Collaboration - Version control allows us to define formalized ways we can work together and share writing and code. For example merging together sets of changes from different parties enables co-creation of documents and software across distributed teams.
- Versioning - Having a robust and rigorous log of changes to a file, without renaming files (v1, v2, final_copy)
- Rolling Back - Version control allows us to quickly undo a set of changes. This can be useful when new writing or new additions to code introduce problems.
- Understanding - Version control can help you understand how the code or writing came to be, who wrote or contributed particular parts, and who you might ask to help understand it better.
- Backup - While not meant to be a backup solution, using version control systems mean that your code and writing can be stored on multiple other computers.
There are many more reasons to use version control, and we’ll explore some of them for research data management, but first let’s learn a bit about a popular version control tool called Git.
What are Git and Codeberg?
We often hear the terms Git and Codeberg (or GitHub, GitLab, …) used interchangeably but they are different things.
Git is one of the most widely used version control systems in the world. It is a free, open source tool that can be downloaded to your local machine and used for logging all changes made to a group of designated computer files (referred to as a “git repository” or “repo” for short) over time. It can be used to control file versions locally by you alone on your computer, but is perhaps most powerful when employed to coordinate simultaneous work on a group of files shared among distributed groups of people.
Rather than emailing documents with tracked changes and some comments and renaming different versions of files (example.txt, exampleV2.txt, exampleV3.txt) to differentiate them, we can use Git to save (or in Git parlance, “commit”) all that information with the document itself. This makes it easy to get an overview of all changes made to a file over time by looking at a log of all the changes that have been made. And all earlier versions of each file still remain in their original form: they are not overwritten, should we ever wish to “roll back” to them.
Git was originally developed to help software developers work collaboratively on software projects, but it can be and is used for managing revisions to any file type on a computer system, including text documents and spreadsheets. Once installed, interaction with Git is done through the Command Prompt in Windows, or the Terminal on Mac/Linux. Since Word documents contain special formatting, Git unfortunately cannot version control those, nor can it version control PDFs, though both file types can be stored in Git repositories.
Distributed version control
Git is a distributed version control system: every copy of a repository – on your laptop, on a colleague’s computer or on Codeberg – contains the complete history of the project. You can work and commit offline and synchronise with the other copies later. No copy is technically special; it is only by agreement that a team treats one of them, for example the repository on Codeberg, as the shared, central one.
How can Git help with research data management?
- It documents how your data, scripts and documentation changed over time, and who changed what and why
- It lets you go back to earlier versions without keeping multiple
copies of files (
data_final_v2_corrected.csv) - It makes your work reproducible: you can refer to the exact version of a script or document that produced a result
Codeberg on the other hand is a website for hosting and sharing Git repositories remotely. It offers a web interface for browsing files and their history, and adds features for working together, such as issues, pull requests, wikis and websites. Codeberg is run by Codeberg e.V., a non-profit association based in Berlin, Germany. It is funded by donations, built on the free software Forgejo and dedicated to hosting free and open content: open source software, but also documentation, teaching materials like this lesson, and research projects.
There are many other Git hosting services that offer similar features, such as GitHub, GitLab (often run by universities and research institutions as their own instance) and Bitbucket. Because they all build on Git, almost everything you learn in this lesson applies to them as well: only the buttons in the web interface look a little different.
Why Codeberg?
We use Codeberg in this lesson because it is a non-profit, community-run platform hosted in the EU, it is built entirely on free software, and it does not track its users or use their content for commercial purposes. For research and teaching materials that are meant to be shared openly, this makes it a good fit.
Codeberg is intended for free and open content. Please check the Terms of Use before you use it for your own projects.
How can Codeberg help with research data management?
- A place to share code, documentation and small datasets, and to collaborate on them with colleagues inside and outside your institution
- A place to discover and reuse (“fork”) openly licensed projects, for example analysis scripts or metadata schemas
- Issues and pull requests document discussions and decisions together with the project
- A simple way to publish a project website with Codeberg Pages
Uses in Research Data Management
Consider these common scenarios:
Scenario 1: A research group cleaning a shared dataset
A doctoral researcher has exported survey data as a CSV file for cleaning. Several people in the group work on the data and the scripts that process it, so they need to make sure that edits don’t get lost or overwrite each other. They also need to be able to undo changes, keep the raw data unchanged, and explain later in a publication how the data was processed.
The group can use Git to record every change to the cleaning scripts and the documentation, together with a message explaining why it was made. By hosting the project on Codeberg, they can review each other’s changes before they are merged, and discuss problems they find in the data in issues. Months later, the history still shows who changed what, when and why.
Scenario 2: Reusing another group’s workflow
A data steward wants to help a research group set up a data processing workflow. She finds a project on Codeberg in which another institute has published scripts, a README and a metadata template for exactly this type of data under an open licence.
Instead of starting from scratch, she can fork the project, adapt it to the new group’s needs, and keep track of all changes. If she fixes a bug along the way, she can suggest the fix to the original project with a pull request, so that everybody benefits.
Scenario 3: Documenting and publishing a data project
A project team wants to describe their dataset, its variables and the conditions for reuse on a small website, and keep this documentation up to date while the project continues.
They keep the documentation as text files in a Git repository and publish them with Codeberg Pages. Every change to the documentation is versioned, so readers can see what changed, and the team can link to the exact version that belonged to a data publication.
- Version control helps track changes to files and projects
- Git and Git hosting platforms like Codeberg are not the same
Content from Getting started with Git
Last updated on 2026-10-21 | Edit this page
Estimated time: 25 minutes
Overview
Questions
- What are repositories and how are they created?
- What do
addandcommitmean? - How do I check the status of my repository?
Objectives
- apply Git to turn a directory into a repository
- apply the two steps
addandcommitto record changes to files - apply
git statusto check the state of a repository - apply a README file as a method of documenting a project
Setting up Git
When we use Git on a new computer for the first time, we need to configure a few things. The basic elements of a configuration for Git are:
- your name and email address,
- what your preferred text editor is,
- the name of your default branch (branches are an important component of Git that we will cover later).
To start we will check in on our current Git configuration. Open your shell terminal window and type:
On MacOS, without any configuration your output might look like this:
OUTPUT
credential.helper=osxkeychain
init.defaultbranch=mainIf you followed our instructions for installing Git for Windows, your output might look like this:
OUTPUT
diff.astextplain.textconv=astextplain
filter.lfs.clean=git-lfs clean -- %f
filter.lfs.smudge=git-lfs smudge -- %f
filter.lfs.process=git-lfs filter-process
filter.lfs.required=true
http.sslbackend=schannel
core.autocrlf=true
core.fscache=true
core.symlinks=true
core.editor=nano.exe
pull.rebase=false
credential.helper=manager
credential.https://dev.azure.com.usehttppath=true
init.defaultbranch=masterIf you are using Linux or WSL 2 on Windows, you might not see any output at all.
If you have different output, then you may have your Git configured already. If you have not configured Git, we will do that together now. First, we will tell Git our user name and email.
Please note: Use the same email address in your Git configuration in
the shell as you entered into Codeberg when you created your Codeberg
account. Later in the lesson we will be using Codeberg, and it uses the
email address to link your commits to your account. Keep in mind that
the email address in your commits will be publicly visible once you
share them. If you are concerned about privacy, you can use the private
noreply address that Codeberg shows in your account
settings under “Account” instead.
Type these two commands into your shell, replacing
Your Name and the email address with your own:
BASH
$ git config --global user.name "Your Name"
$ git config --global user.email "yourname@domain.name"If you enter the commands correctly, the shell will merely return a command prompt and no messages. To check your work, ask Git what your configuration is using the same command as above:
OUTPUT
user.name=Your Name
user.email=yourname@domain.nameLet’s also set our default text editor. A text editor is necessary with some of your Git work, and the default from Git is Vim, which is a text editor that is hard to learn at first. Therefore, we recommend setting a simpler text editor in your Git configuration for this lesson.
Text editors
There are a lot of text editors to choose from, and a lot of people are enthusiastic about their preferences.
Nano is a good choice because it works on Mac, Windows, and Linux; it runs directly in your shell; and has on-screen reminders of how to use it. If you followed our instructions for installing Git for Windows, it should already be your default editor.
Vi and Vim also run directly in the shell and have many powerful features, but are less beginner-friendly.
If you will be using Git or the Shell with a group of people for a project or for work, asking for recommendations or preferences can help you pick an editor to get started with. If you already have your favorite, then you can set it as your default editor with Git.
Any text editor can be made default by adding the correct file path
and command line options (see the Git
documentation). However, the simplest core.editor value
is "nano -w", which will run the Nano text editor directly
in your shell. To select it, type the following into your shell:
Lastly, we need to make sure the name of our default branch is set to
main, as that is what Codeberg and most other Git hosting
platforms use. To do this, type the following into your shell:
You may already have seen a setting for
init.defaultbranch when you looked at your configuration
earlier, overriding Git’s internal default. If your system configuration
sets the default branch to main, you don’t necessarily have
to set it again yourself, but doing so protects you from any
system-level changes.
Creating a repository
A Git repository is a data structure used to track
changes to a set of project files over time. Repositories are stored
within the same directory as these project files, in a hidden directory
called .git. We can create a new git repository either by
using Codeberg’s web
interface, or via the command line. Let’s use the command line to
create a git repository for the experiments that we’re going to do
today.
We will use the directory my-git-repo-<name> on
the Desktop that we created in the shell episodes. Let’s make sure we
are in it:
OUTPUT
/Users/riley/Desktop/my-git-repo-rileyThe ~ is a shortcut for your home directory, so this
command works no matter where you are at the moment.
Using Git
One of the main barriers to getting started with Git is understanding the terminology necessary to executing commands. Although some of the language used in Git aligns with common-use words in English, other terms are not so clear. The best way to learn Git terminology - which consists of a number of verbs such as add, commit and push (preceded by the word ‘git’) - is to use it, which is what we will be doing during this lesson. We will explain these commands as we proceed from setting up a new version-controlled project to publishing our own website.
On a command line interface, Git commands are written as
git verb options, where verb is what we
actually want to do and options is additional optional
information which may be needed for the verb. So let’s get
started with our setup.
We will now create an empty git repository to track changes to our project. To do this we will use the git init command, which is short for initialise.
OUTPUT
Initialized empty Git repository in /Users/riley/Desktop/my-git-repo-riley/.git/The my-git-repo-<name> directory is now a git
repository.
If we run the ls command now, we only see our
README.md; however, adding the -a flag for all
files via ls -a will show all hidden files, which in this
case includes the new hidden directory .git. Flags can be
thought of as command line options that can be added to shell
commands.
Note that whenever we use git via the command line, we need to
preface each command (or verb) with git, so that the
computer knows we are trying to get git to do something, rather than
some other program.
Displaying the current project’s status
We can run the git status command to display the current
state of a project. Let’s do that now.
OUTPUT
On branch main
No commits yet
Untracked files:
(use "git add <file>..." to include in what will be committed)
README.md
nothing added to commit but untracked files present (use "git add" to track)The output tells us that we are on the main branch and that there are no commits yet.
Branches and commits
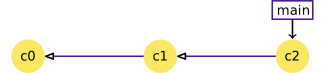
Commits in Git are like snapshots of our project. They are ordered into sequences, or “branches”, with each commit pointing back to the one before it in the branch. Git keeps track of the last commit in each branch with a special label; in this lesson we mostly use one branch with the label “main”.
Two steps: Adding and committing
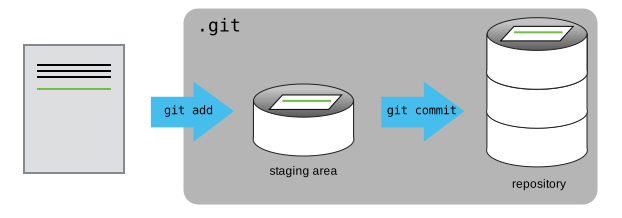
We will now save our first project file, the README.md
we created in the shell episodes, in the repository. This is a two-step
process. First, we add any files for which we want to
save the changes to a staging area, then we commit
those changes to the repository. This two-stage process gives us
fine-grained control over what should and should not be included in a
particular commit.
The status above is telling us that git has noticed a file in our
directory that we are not yet tracking (an untracked file).
With colourised output, the filename will appear in red. To change this,
and to tell Git we want to track any changes we make to
README.md, we use git add.
This adds our Markdown file to the staging area (the
area where git checks for file changes). To confirm this we want to use
git status again.
OUTPUT
On branch main
No commits yet
Changes to be committed:
(use "git rm --cached <file>..." to unstage)
new file: README.mdIf we are using colourised output, we will see that the filename has changed colour (from red to green). Git also tells us that there is a new file to be committed but, before we do that, let’s add some more text to the file.
We will open the file README.md with a text editor. If
you set Nano as your core.editor value, this would be a
good time to try it out:
If you don’t want to try Nano, use whatever text editor you feel comfortable with (e.g. Notepad on Windows or TextEdit on macOS) to open the file.
When you have the file open, you see the two lines we wrote with
echo. Add a third line, for example
Created in a Git and Codeberg workshop.. Then save the file
and close the text editor.
When showing how to edit README.md for the first time,
Nano is the most convenient editor to use – you don’t have to leave the
shell and it should work for everyone – but few learners will be fully
confident with it. Take them step-by-step through one of the two ways of
saving and closing the file:
- Ctrl + X to close the file; Y to save the file; Enter to keep the same filename.
- Ctrl + O to save the file; Enter to keep the same filename; Ctrl + X to close the file.
You could also keep a file manager window open (e.g. File Explorer, Finder, Files/Nautilus, Dolphin) to demonstrate locating the file and opening it in a suitable GUI text editor. Look out for learners who need help with this.
Now, let’s check if Git has spotted the changes:
OUTPUT
On branch main
No commits yet
Changes to be committed:
(use "git rm --cached <file>..." to unstage)
new file: README.md
Changes not staged for commit:
(use "git add <file>..." to update what will be committed)
(use "git checkout -- <file>..." to discard changes in working directory)
modified: README.mdThis lets us know that git has indeed spotted the changes to our file, but that it hasn’t yet staged them, so let’s add the new version of the file to the staging area.
Now we are ready to commit our first changes. Commit is similar to ‘saving’ a file to Git. However, compared to saving, a commit provides a lot more information about the changes we have made, and this information will remain visible to us later.
OUTPUT
[main (root-commit) e9e8fd3] Add README.md
1 file changed, 3 insertions(+)
create mode 100644 README.mdWe can see that one file has changed and that we made three
insertions, which were the three lines of our README.md. We
can also see the commit message ‘Add README.md’, which we added by using
the -m flag after git commit. The commit
message is used to record a short, descriptive, and specific summary of
what we did to help us remember later on without having to look at the
actual changes. If we just run git commit without the
-m option, Git will launch Nano (or whatever other editor
we configured as core.editor) so that we can write a longer
message.
Having made a commit, we now have a permanent record of what was changed, and git has also recorded some additional metadata: who made the commit (you!) and when the commit was made (timestamp). You are building a mini-history of your process of working with the files in this directory.
More on the Staging Area
If you think of Git as taking snapshots of changes over the life of a
project, git add specifies what will go in a
snapshot (putting things in the staging area), and
git commit then actually takes the snapshot, and
makes a permanent record of it (as a commit). If you don’t have anything
staged when you type git commit, Git will prompt you to use
git commit -a or git commit --all, which is
kind of like gathering everyone to take a group photo! However,
it’s almost always better to explicitly add things to the staging area,
because you might commit changes you forgot you made. (Going back to the
group photo simile, you might get an extra with incomplete makeup
walking on the stage for the picture because you used -a!)
Try to stage things manually, or you might find yourself searching for
“git undo commit” more than you would like!
At the moment, our changes are only recorded locally, on our computer. If we wanted to work collaboratively with someone else they would have no way of seeing what we’ve done. We will fix that in the next episode by using Codeberg to share our work.
- When you initialize a Git repository in a directory, Git starts tracking the changes you make inside that directory.
- This tracking creates a history of the way the files have changed over time.
- Git uses a two-step process to record changes to your files. Changes to files must first be added to the staging area, then committed to the Git repository.
Content from Sharing your work
Last updated on 2026-10-21 | Edit this page
Estimated time: 75 minutes
Overview
Questions
- How can I use Git and Codeberg to share my work?
- How do I link a local Git repository to Codeberg?
- How do I move changes between a local Git repository and a Codeberg repository?
- How can I see the differences between my current file and my most recent commit?
Objectives
- apply Codeberg to create a remote repository
- apply SSH keys to authenticate securely with Codeberg
- apply
pushandpullto exchange changes between a local and a remote repository - apply
git diffandgit logto inspect changes and the history of a repository - explain best practices such as meaningful commit messages and the role of licences for reuse
The power of sharing
The real power of Git lies in being able to share your work with others and in being able to work collaboratively. The best way to do this is to use a remote hosting platform. For this lesson, we are using Codeberg. Let’s log in there now.
Create a repository on Codeberg
Once we have logged in to Codeberg, we can create a new repository by clicking the + icon in the upper-right corner of any page then selecting New repository. Let’s do this now.
- Click “New repository”
Clicking “New repository” will take you to a creation page with different options. For this workshop, we are not using most of the options available.
- Name your repository like your local directory:
my-git-repo-<name>, for examplemy-git-repo-riley. - Leave the repository public (do not tick “Make repository private”), so that your partner can see it later in the lesson.
Codeberg will offer to initialize the repository with a README, a
license or a .gitignore file. Do not do any of that for now
– we want you to start with a completely empty repository on
Codeberg.
- Click the “Create repository” button.
Choosing a license
When you are ready to use Codeberg to host your own work, you should review the different license options. Choosing a license is an important part of openly sharing your creative and research work online. For help in wading through the many types of open source licenses, please visit https://choosealicense.com/.
Connecting your local repository to the Codeberg repository
The next page that Codeberg displays contains some information to
help you connect your repository on Codeberg with your local repository
(on your own computer). To make this connection, we want to tell our
local repository that Codeberg is the remote repository. In
order to do that we need the information that Codeberg displays in the
“Quick guide” on this page.
We will use the Secure Shell (SSH) protocol for this lesson, so
please make sure that “SSH” is selected next to the address box and that
the address starts with git@codeberg.org:. It will look
something like this:
HTTPS vs. SSH
We use SSH here because, while it requires some additional configuration, it is a security protocol widely used by many applications. The steps below describe SSH at a minimum level for Codeberg.
In the previous episode we created a local repository on our own computer. Now we have also created a remote repository on Codeberg. But at this point, the two are completely isolated from each other. We want to link them together to synchronize them and share our project with the world.
To connect the repository on our own computer (local) to the repository we just created on Codeberg, we will use the commands provided by Codeberg under the heading “Pushing an existing repository from the command line”.
Let’s use these instructions now. Move back to your shell application and enter the first command:
Make sure to use the URL of your actual repository: the only
differences should be your username instead of yourname and
your name instead of <name>.
Let’s breakdown the elements of the command. All commands related to
Git in the shell start by invoking the Git language by typing
git at the start. remote add is the command in
the Git language we use to configure a remote repository, e.g., another
Git repository that contains the same content as our local repository,
but that is not on our computer. origin is the nickname
we’re telling our local machine to use to for the following long web
address. After we enter this command, we can use origin to
refer to this specific repository on Codeberg instead of the URL.
We can check that it is set up correctly with the command:
OUTPUT
origin git@codeberg.org:<your_codeberg_username>/my-git-repo-<name>.git (fetch)
origin git@codeberg.org:<your_codeberg_username>/my-git-repo-<name>.git (push)SSH Background and Setup
We still need to do a little more setup before we can actually connect to this remote repository. We need to set up a way for our local computer to authenticate with Codeberg so that Codeberg recognizes our computer as belonging to the same person who owns the Codeberg repository.
We will use SSH as our authentication method. SSH stands for Secure SHell protocol. SSH is a cryptographic network protocol that allows secure communication between computers using an otherwise insecure network.
SSH uses what is called a key pair – two keys that work together to validate access. One key is used publicly (the public key) and the other key is kept private (the private key).
You can think of the public key as a padlock, and only you have the key (the private key) to open it. You use the public key where you want a secure method of communication, such as your Codeberg account. You give this padlock, or public key, to Codeberg and say “lock the communications to my account with this so that only computers that have my private key can unlock communications and send Git commands as my Codeberg account.”
What we will do now is the minimum required to set up the SSH keys and add the public key to a Codeberg account. I’m not going to lie, this is a bit tedious and confusing. But you have to do it to get to the fun part, so hang in there.
The first thing we are going to do is check if this has already been done on the computer you’re on.
Keeping your keys secure
You shouldn’t really forget about your SSH keys, since they keep your account secure. It’s good practice to audit your secure shell keys every so often. Especially if you are using multiple computers to access your account.
We will run the list command (ls) to check what key
pairs already exist on your computer. In our command we use the
~ as the shorthand for “my home directory.”
Your output is going to look a little different depending on whether or not SSH has ever been set up on the computer you are using.
If you have not set up SSH, your output might look like this:
OUTPUT
ls: cannot access '/c/Users/YourName/.ssh': No such file or directoryIf SSH has been set up on the computer you’re using, the public and
private key pairs will be listed. The file names are either
id_ed25519/id_ed25519.pub or
id_rsa/id_rsa.pub depending on how the key
pairs were set up.
If you do not have SSH set up, let’s set it up now. Use this command to create key pairs:
OUTPUT
Generating public/private ed25519 key pair.
Enter file in which to save the key (/c/Users/YourName/.ssh/id_ed25519):We want to use the default file, so just press Enter.
OUTPUT
Created directory '/c/Users/YourName/.ssh'.
Enter passphrase (empty for no passphrase):Your computer is now asking you for a passphrase to protect this SSH key pair. We recommend that you use a passphrase and that you make a note of it. There is no “reset my password” option for this setup. If you forget your passphrase, you have to delete your existing key pair and do this setup again. It’s not a big deal, but easier if you don’t have to repeat it.
OUTPUT
Enter same passphrase again:After entering the same passphrase a second time, you will receive the confirmation
OUTPUT
Your identification has been saved in /c/Users/YourName/.ssh/id_ed25519
Your public key has been saved in /c/Users/YourName/.ssh/id_ed25519.pub
The key fingerprint is:
SHA256:SMSPIStNyA00KPxuYu94KpZgRAYjgt9g4BA4kFy3g1o yourname@domain.name
The key's randomart image is:
+--[ED25519 256]--+
|^B== o. |
|%*=.*.+ |
|+=.E =.+ |
| .=.+.o.. |
|.... . S |
|.+ o |
|+ = |
|.o.o |
|oo+. |
+----[SHA256]-----+The “identification” is actually the private key. You should never share it. The public key is appropriately named. The “key fingerprint” is a shorter version of a public key.
Now that we have generated the SSH keys, we will find the SSH files when we check.
OUTPUT
drwxr-xr-x 1 YourName 197121 0 Jul 16 14:48 ./
drwxr-xr-x 1 YourName 197121 0 Jul 16 14:48 ../
-rw-r--r-- 1 YourName 197121 419 Jul 16 14:48 id_ed25519
-rw-r--r-- 1 YourName 197121 106 Jul 16 14:48 id_ed25519.pubNow we need to give our public key (the padlock) over to Codeberg.
First, we need to copy the public key. Be sure to include the
.pub at the end, otherwise you’re looking at the private
key.
OUTPUT
ssh-ed25519 AAAAC3NzaC1lZDI1NTE5AAAAIDmRA3d51X0uu9wXek559gfn6UFNF69yZjChyBIU2qKI yourname@domain.nameCopy that entire line of output, and we will paste the copied text into Codeberg in the next step.
Now, going to codeberg.org, click on your profile icon in the top right corner to get the drop-down menu. Click “Settings,” then on the settings page, click “SSH / GPG keys” in the menu on the left side. In the “Manage SSH keys” section, click the “Add key” button. Now, you can add a key name (a person might use the name “My 2026 work laptop,” just a little description to remind themselves which computer this public key connects to). Paste your SSH key into the “Content” field, and click “Add key” to complete the setup.
Now that we’ve set that up, let’s check our authentication from the command line.
The first time you connect, SSH will ask whether you trust the host
codeberg.org. You can compare the fingerprint shown with
the ones published in the Codeberg
documentation, then type yes and press
Enter.
OUTPUT
Hi there, YourName! You've successfully authenticated with the key named My 2026 work laptop, but Forgejo does not provide shell access.
If this is unexpected, please log in with password and setup Forgejo under another user.Pushing changes
Now we have established a connection between the two repositories,
but we still haven’t synchronized their content, so the remote
repository is still empty. To fix that, we will have to “push” our local
changes to the Codeberg repository. We do this using the
git push command:
OUTPUT
Enumerating objects: 3, done.
Counting objects: 100% (3/3), done.
Writing objects: 100% (3/3), 226 bytes | 226.00 KiB/s, done.
Total 3 (delta 0), reused 0 (delta 0), pack-reused 0
To codeberg.org:<your_codeberg_username>/my-git-repo-<name>.git
* [new branch] main -> main
branch 'main' set up to track 'origin/main'.The nickname of our remote repository is “origin” and the default
local branch name is “main”. The -u flag tells git to
remember the parameters, so that next time we can simply run
git push and Git will know what to do.
Pushing our local changes to the Codeberg repository is sometimes
referred to as “pushing changes upstream to Codeberg”. The
word upstream here comes from the git flag we used earlier
in the command git push -u origin main. The flag
-u refers to --set-upstream, so when we say
pushing changes upstream, it refers to the remote repository.
If you set a passphrase for your SSH key, you will be prompted to enter it to complete the command.
When we do a git push, we will see Git ‘pushing’ changes
upstream to Codeberg. Because our file is very small, this won’t take
long but if we had made a lot of changes or were adding a very large
repository, we might have to wait a little longer. We can check where
we’re at with git status.
OUTPUT
On branch main
Your branch is up-to-date with 'origin/main'.
nothing to commit, working tree cleanThis output lets us know where we are working (the main branch). We can also see that we have no changes to commit and everything is in order.
We can use the git diff command to see changes we have
made before making a commit. Open README.md with any text
editor and enter some text on a new line, for instance “A new line” or
something else. We will then use git diff to see the
changes we made:
OUTPUT
diff --git a/README.md b/README.md
index aed0629..989787e 100644
--- a/README.md
+++ b/README.md
@@ -1,3 +1,4 @@
# My Git repository
This is where I practise Git.
Created in a Git and Codeberg workshop.
+A new lineThe command produces lots of information and it can be a bit overwhelming at first, but let’s go through some key information here:
- The first line tells us that Git is producing output similar to the
Unix
diffcommand, comparing the old and new versions of the file. - The second line tells exactly which versions of the file Git is
comparing;
aed0629and989787eare unique computer-generated identifiers for those versions. - The third and fourth lines once again show the name of the file being changed.
- The remaining lines are the most interesting; they show us the actual differences and the lines on which they occur. In particular, the + markers in the first column show where we have added lines.
We can now commit these changes:
If we are very forgetful and have already forgotten what we changed,
git log allows us to look at what we have been doing with
our git repository (in reverse chronological order, with the very latest
changes first).
OUTPUT
commit 8e2eb9920eaa0bf18a4adfa12474ad58b765fd06
Author: Your Name <your_email>
Date:   Mon Jun 5 12:41:45 2017 +0100

    Add another line

commit e9e8fd3f12b64fc3cbe8533e321ef2cdb1f4ed39
Author: Your Name <your_email>
Date:   Fri Jun 2 18:15:43 2017 +0100

    Add README.md
This shows us the two commits we have made and shows the messages we wrote. It is important to try to use meaningful commit messages when we make changes. This is especially important when we are working with other people who might not be able to guess as easily what our short cryptic messages might mean. Note that it is best practice to always write commit messages in the imperative (e.g. ‘Add README.md’, rather than ‘Adding README.md’).
Pushing changes (again)
Now, let’s have a look at the repository on Codeberg again (that is,
https://codeberg.org/some-researcher/my-git-repo-<name>
with some-researcher replaced with your username). We see
that the README.md file is there, but there is only one
commit:
Codeberg shows the content of README.md below the list
of files: it contains our three lines, but not the new line we just
added.
This is because we haven’t yet pushed our local changes to the remote repository. This might seem like a mistake in design but it is often useful to make a lot of commits for small changes so you are able to make careful revisions later and you don’t necessarily want to push all these changes one by one.
Another benefit of this design is that you can make commits without being connected to internet.
But let’s push our changes now, using the git push
command:
OUTPUT
Enumerating objects: 5, done.
Counting objects: 100% (5/5), done.
Writing objects: 100% (3/3), 272 bytes | 272.00 KiB/s, done.
Total 3 (delta 0), reused 0 (delta 0), pack-reused 0
To codeberg.org:<your_codeberg_username>/my-git-repo-<name>.git
   e9e8fd3..8e2eb99  main -> main
And let’s check on Codeberg that we now have 2 commits there.
Branches can be configured with an “upstream” branch (a branch on a
remote repository), which is used automatically for push
and pull operations.
The main branch’s upstream wasn’t set when we created
it. The -u (or --set-upstream) flag tells
git push which remote branch to use; it also sets the
remote branch as the local branch’s upstream. Once we’ve set it, we
don’t need to specify the remote branch in future push and
pull operations. This saves on typing and means we won’t
push to or pull from the wrong remote
branch.
Pulling changes
When working with others, or when we’re making our own changes from different machines, we need a way of pulling those remote changes back into our local copy. For now, we can see how this works by making a change on the Codeberg website and then ‘pulling’ that change back to our computer.
Let’s go to our repository on Codeberg and make a change. Click on
README.md in the list of files and then on the pencil icon
(“Edit file”). Add a line, for example a sentence about what you would
like to use Git for. Scroll to the bottom, make sure “Commit directly to
the main branch” is selected and click “Commit changes”
(the default commit message will be “Update README.md”, which is fine
for our purposes).
The README file
It is good practice to add a README file to each project to give a brief overview of what the project is about. If you put your README file in your repository’s root directory, Codeberg will recognize and automatically surface your README to repository visitors
Our local repository is now out of sync with our remote repository,
so let’s fix that by pulling the remote changes into our local
repository using the git pull command.
OUTPUT
remote: Enumerating objects: 4, done.
remote: Counting objects: 100% (4/4), done.
remote: Compressing objects: 100% (2/2), done.
remote: Total 3 (delta 0), reused 0 (delta 0), pack-reused 0
Unpacking objects: 100% (3/3), done.
From codeberg.org:<your_codeberg_username>/my-git-repo-<name>
   8e2eb99..0f5a7b0  main     -> origin/main
Updating 8e2eb99..0f5a7b0
Fast-forward
 README.md | 1 +
 1 file changed, 1 insertion(+)
The above output shows that we have fast-forwarded our local
repository to include the change to README.md. We can
confirm this with the shell command we already know:
When we begin collaborating on more complex projects, we may have to consider more aspects of git functionality, but this should be a good start. In the extended version of this workshop, we look more closely at collaborating with others on Codeberg using issues and pull requests.
- remote repositories on Codeberg help you collaborate and share your work
-
pushis a Git verb for sending changes from the local repository to a remote repository -
pullis a Git verb for bringing changes from a remote repository to the local repository -
diffis a Git verb for viewing the difference between an edited file and the file’s most recent commit
Content from Review
Last updated on 2026-10-21 | Edit this page
Estimated time: 25 minutes
Overview
Questions
- How can I cement my understanding of Git’s functions?
Objectives
- explain Git commands in everyday language
- explain the functions of Git by drawing or sketching them
Let’s review
It is likely that some things won’t have stuck from the last hour. To try to reinforce how things work we can work in groups to develop diagrams to illustrate Git functions and language. This should make carrying out more complicated aspects of Git clearer in our heads.
If you are teaching this lesson over Zoom, you may find it preferable to run the review exercise in one large group instead of splitting out into breakout rooms. One way to adapt the exercise is to set up a shared online drawing board using a service such as Miro, and share the link so all the learners can access it.
Ask the learners to recall the commands and concepts they’ve used and add them to the board using, say, green sticky notes for Shell commands and yellow sticky notes for Git commands. Then use this as the basis for a quiz: ask the learners to explain what a command does, or describe an action and ask which command is needed. If you ask the learners to reply using the Zoom chat or Q&A, rather than verbally, it gives everyone a chance to answer.
As a next step, work together on some diagrams to illustrate key concepts such as commits and branches, the staging area, or how origin and cloned repositories relate. Use background shapes, arrows, lines and text as appropriate.
Finally, ask learners to work individually on their own sections of the drawing board; you could keep a topic back from the group activity specifically for this part of the exercise, or ask the learners to come up with their own versions of the collaborative drawings.
How would you explain it?
In groups:
- make a list of commands and concepts we’ve discussed in the first hour
- try to come up with synonyms or explanations for what the commands are doing
- try to ‘draw’ what different commands mean
- come up with your own analogies and diagrams to explain how Git works.
Here are some tips for illustrating the commands and concepts we’ve used with Git:
- try to express Git commands in a ‘non-Git’ way
- try to visualise what commits are doing to your repository
- sketch out how information flows from one repository to another.
Be as creative and artistic as you like!
If you want to practise more, feel free to keep making changes to your file and committing those changes. If you want to explore more git commands, search for some more online or visit the lesson resources.
- the language of Git can be confusing and intimidating
- rephrasing commands and drawing concepts can clarify Git’s workflow
Content from Managing a project with issues
Last updated on 2026-10-21 | Edit this page
Estimated time: 40 minutes
Overview
Questions
- How can I use Codeberg to plan and track the work in a project?
- How can I report a problem or make a suggestion for someone else’s project?
Objectives
- apply issues to report problems and suggest tasks in someone else’s repository
- apply labels, assignees, milestones and project boards to plan and track the tasks in a project
- apply references to commits, issues and people in comments
- explain how the history of issues makes a project transparent and traceable
Extended workshop
This episode and the next one are part of the extended
(lunch-to-lunch) version of this workshop. They build on the
my-git-repo-<name> repositories that you created and
pushed to Codeberg in the previous episodes.
For the exercises, find a partner and exchange your Codeberg usernames and the names of your repositories.
What are issues?
So far we have used Codeberg to store and share files. But a project is more than its files: there are tasks to do, problems to fix, questions to answer and decisions to document. Codeberg has a feature for this called issues.
An issue is like a ticket or a to-do item that belongs to a repository. It has a title, a description, and a discussion below it, and it is either open (still to be done) or closed (done or no longer relevant). By default, anybody with a Codeberg account can open an issue in a public repository. This makes sense: people can report problems and ask questions, even if they are not allowed to change anything themselves.
In research data management, issues are useful for example to
- collect tasks for a data publication (“Add README with variable descriptions”, “Choose a license”),
- report problems with a dataset (“Column
agecontains negative values insurvey_2026.csv”), - document decisions and the discussion that led to them, so that they can be found again later.
Issues in public repositories are public
Everybody can read the issues of a public repository, and closed issues stay visible. Never put personal data, passwords or other confidential information into an issue.
Create an issue
Your partner’s repository has a README, but it doesn’t say who works on the project. You would like to suggest adding a list of contributors – and you would like to help with it and be on that list yourself. Since it’s your partner’s project, you don’t change it directly, but open an issue in their repository to make your suggestion.
We navigate to the repository of our partner,
https://codeberg.org/some-researcher/my-git-repo-<partner>
(with some-researcher replaced by our partner’s username
and <partner> by their name). We click the tab
“Issues” and then the button “New issue”.
We give the issue a short, descriptive title, for example “Add a list of contributors”, and a description:
MARKDOWN
The people who contribute to this project should be mentioned in its documentation.
Their names could be listed in one of the following locations:

- a section in `README.md`
- a separate `CONTRIBUTORS.md` file
The description is written in Markdown, just like our
README.md. Click on “Preview” above the text field to see
how it will look.
Markdown code spans and blocks
Markdown provides syntax for formatting text in a monospaced font. This is usually used for file names, commands and code.
For a monospaced snippet within a normal paragraph, enclose the snippet in single backticks, for example
For a whole block of monospaced text, for example some lines of code or the output of a command, start and end the block with a line consisting of three backticks:
On the right side of the form you may see fields for labels, milestones, projects and assignees. As we are not a collaborator in our partner’s repository, we can’t set most of them – that’s the job of the repository owner, which we’ll come to in a moment.
We click “Create issue”. This takes us to the new issue’s page. At
the top we see its title, followed by its number, #1.
Issue numbers
On Codeberg, issues and pull requests share the same numbering in a
repository. Our issue is the first one in our partner’s repository, so
it gets the number #1; the next issue or pull request will
be #2. We can refer to any issue or pull request with its
number, as we will see.
Comment on an issue and reference a commit
We want to add a concrete suggestion where the list could be linked: in the README, which our partner created in their first commit. So we write a comment that refers to this commit.
When we mention a commit by its identifier, Codeberg automatically turns it into a link to that commit. To find the identifier, we open our partner’s repository in a second browser tab and click on “Commits”. The commit “Add README.md” is at the bottom of the list, with a short sequence of numbers and letters on the right: the beginning of the commit’s identifier, also called its hash or SHA. Next to it is a button to copy the full identifier.
Back on the issue page, we write a comment like this, pasting the identifier of the commit:
MARKDOWN
The README was added in commit e9e8fd3f12b64fc3cbe8533e321ef2cdb1f4ed39 – it could link to the list of contributors.
I'm happy to help with this and would like to be on the list, too.
and click “Comment”. Our comment appears below the description, and Codeberg shows a shortened version of the identifier as a link.
Mentioning people, issues and commits
Codeberg recognises some special references in issues, comments and pull requests:
-
@usernamementions a person, who will be notified, -
#1links to issue or pull request number 1 in the same repository, - a commit identifier links to that commit.
Triage: labels, assignees and milestones
In the meantime, our partner has opened an issue in our repository, too. Now we switch roles: as the owner of our repository, we are responsible for sorting incoming issues. This is often called triage.
We go to our own my-git-repo-<name> repository,
click the tab “Issues” and open the issue from our partner.
Labels
Labels are coloured tags that help to group and filter issues, for example by type (“bug”, “question”, “documentation”) or by status (“in progress”, “needs discussion”).
Our repository doesn’t have any labels yet, so we create some first.
On the “Issues” tab we click on “Labels”. Codeberg offers to load a
predefined set of labels: select the “Default” set and confirm. This
creates commonly used labels such as bug,
enhancement and question.
To add our own label, we click “New label”, call it
documentation, choose a colour and click “Create
label”.
Back on the issue, we click on “Labels” in the sidebar on the right
and select documentation.
Assignees
The “Assignees” field shows who is responsible for working on an issue. Only people with write access to the repository can be assigned, so we assign ourselves: click on “Assignees” in the sidebar and select your own username.
Milestones
A milestone groups issues that should be done by a certain point, for example “README complete” or, in a data project, “Data publication v1.0”. On the “Issues” tab, click “Milestones”, then “New milestone”. Give it a title and, optionally, a due date and click “Create milestone”. Then add the issue to the milestone in the sidebar of the issue. On the “Milestones” page you can now see how many of the milestone’s issues are already closed.
Project boards
When a project has many issues, it helps to see at a glance what is waiting, what is being worked on and what is done. Codeberg offers project boards for this, also known as Kanban boards.
We click the tab “Projects” in our repository and then “New project”.
No “Projects” tab?
If you don’t see a “Projects” tab, it may be switched off for your repository. You can enable it in the repository “Settings” under “Units” (or “Advanced settings”, depending on the Codeberg version).
We give the project a title, for example “My Git repository”, and choose the template “Basic kanban”. This creates a board with columns such as “To Do”, “In Progress” and “Done”. We click “Create project”.
To put an issue on the board, we open the issue and select our project under “Projects” in the sidebar. Back on the board, the issue appears as a card in the first column. We can now drag the card from one column to another, for example to “In Progress” once we start working on it.
Note that the board is only an overview: moving a card to “Done” does not close the issue. Closing an issue is something we do on the issue itself.
Task lists
Some issues contain several small steps. Markdown task lists turn these into checkboxes:
Codeberg shows the checkboxes in the issue, and in the list of issues you can see how many of them are already ticked.
Close an issue
Below the comment field of every issue there is a button “Close”. If you write something in the comment field first, you can add a final comment when you close the issue. Closed issues no longer appear in the list of open issues, but they are not deleted: you can still find them with the search or the “Closed” filter on the “Issues” tab. This makes issues a searchable record of what was done in a project and why.
Don’t close your partner’s issue yet! In the next episode, we will close it automatically with a pull request that solves it.
Challenge: Issues in your own work
Think about a project you are currently working on (for example a dataset, a publication or a website).
- Write down three things that could be an issue in this project.
- Which labels would be useful to organise them?
- Would a milestone make sense? What would it be called?
If you like, create a new repository on Codeberg for this project and add the issues there. Remember not to include confidential information if the repository is public.
Challenge: Explore the history of an issue
Open the issue that your partner created in your repository and scroll down.
What does Codeberg record in the history of the issue, apart from the comments? Why could this be useful?
Besides comments, Codeberg records events such as adding or removing labels, assigning people, adding the issue to a milestone or project, and closing or reopening the issue – each with the person who did it and when. This makes it easy to follow who did what at which point in time, which is helpful in teams and for documenting a project.
- Issues are used to report problems, ask questions and plan tasks in a repository
- Anybody with a Codeberg account can open issues in a public repository
- Labels, assignees and milestones help to organise issues
- Project boards give an overview of the state of issues
- Commits, issues (
#1) and people (@username) can be referenced in issues and comments - Closed issues remain as a searchable record of the project
Content from Contributing with pull requests
Last updated on 2026-10-21 | Edit this page
Estimated time: 45 minutes
Overview
Questions
- How can I suggest changes to a project on Codeberg?
- How can changes be reviewed before they become part of a project?
Objectives
- apply a fork, a branch and a pull request to contribute changes to another person’s repository
- apply closing keywords to link a pull request to an issue
- analyse proposed changes collaboratively in a pull request review
- explain basic concepts of access control using the example of repository permissions
Pull requests and merge requests
In the previous episode, we used an issue to suggest a change to our partner’s repository. In this episode, we make the change ourselves and propose it to our partner with a pull request, link the pull request to the issue, and go through a review before the changes are merged. We do all of this in the Codeberg web interface.
A pull request asks the owner of a repository to pull changes from another branch (often in a fork) into their repository. Other platforms use different names for the same thing: on GitLab, it is called a merge request.
Our goal is to solve the issue “Add a list of contributors” that we
opened in our partner’s repository in the previous episode: we will add a file
CONTRIBUTORS.md that lists the contributors of the project.
At the same time, our partner does the same in our repository, so we
will be both author and reviewer of a pull request.
Fork the repository
We don’t have write access to our partner’s repository: we can read it, but we can’t change it. So we work in our own copy of it on Codeberg, called a fork. The name comes from a “fork in the road”: once we make changes to our copy, the history of the project splits into two directions. With a pull request, we then ask our partner to pull our changes from the fork into their repository. They can review the changes and decide whether to accept them.
Go to
https://codeberg.org/some-researcher/my-git-repo-<partner>,
with some-researcher replaced by your partner’s username
and <partner> by their name, and click “Fork” in the
upper right part of the screen. Keep the name of the repository: as it
contains your partner’s name, it doesn’t clash with your own repository.
Click “Fork repository” to confirm.
Codeberg takes us to our fork:
https://codeberg.org/<your_codeberg_username>/my-git-repo-<partner>.
Below the repository name it says “forked from
some-researcher/my-git-repo-
Add a file on a new branch
It is good practice to make every contribution on its own
branch, named after what it does. That way,
main stays clean, and you can work on several contributions
at the same time. Codeberg can create the branch for us when we save our
change.
In our fork, we click “Add file” above the list of files and select
“New file”. We name the file CONTRIBUTORS.md and enter
something like:
MARKDOWN
# Contributors

The following people have contributed to this project:

- Some Researcher (owner)
- Conner Learner
with the names replaced by your partner’s name and your own.
All-caps file names
It is customary to give files with information about a
project a name in capital letters, so that they stand out in the list of
files. Examples are README, LICENSE,
CONTRIBUTING (how to contribute) or CITATION
(how to cite the project), often with a file extension such as
.md or .cff.
Below the editor, we enter the commit message “Add CONTRIBUTORS.md”.
Instead of committing directly to main, we select “Create a
new branch for this commit and start a pull request”, name the branch
add-contributors and click “Commit changes”.
Branching and merging
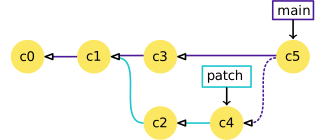
Branches get their name because you can create a new one (say,
“patch”) that splits off from an existing one like “main”, allowing
different sets of changes to be made in parallel. Later on, Git can take
the changes from “patch” and merge them into the “main” branch. This is
exactly what will happen with our branch add-contributors
when the pull request is merged.
Open the pull request
Codeberg now takes us to the page for a new pull request. At the top, it shows which branches will be compared: the target (often called base) on the left, the source on the right. Check that the pull request goes
-
into the
mainbranch of your partner’s repository (some-researcher/my-git-repo-<partner>), -
from the
add-contributorsbranch of your fork (<your_codeberg_username>/my-git-repo-<partner>),
and change the selection if necessary.
Below, Codeberg shows the commits and the changes that will be part of the pull request. The title is filled in with our commit message. In the description, we explain what we did and link the pull request to the issue we opened in the previous episode. Use the number of your issue in your partner’s repository:
Closing issues automatically
If the description of a pull request (or a commit message in it)
contains a phrase like Closes #1, Fixes #1 or
Resolves #1, Codeberg links the pull request to issue
#1 and closes the issue automatically when the pull request
is merged. This saves a few clicks and makes sure that closing the issue
isn’t forgotten. It also documents why an issue was closed.
We click “Create pull request”. This takes us to the page of the pull request in our partner’s repository. It looks similar to an issue page, with a few extra tabs at the top:
- “Conversation”: the description and all comments,
- “Commits”: the commits that are part of the pull request,
- “Files changed”: the changes, shown as a diff like the
output of
git diff.
If we go to the issue in our partner’s repository, we can see that Codeberg has added a note there that the pull request references it.
Pull requests within a team
If you are a collaborator in a repository, you don’t need a fork: you
can create a branch directly in the shared repository and open a pull
request from that branch into main. Many teams work this
way, so that every change is reviewed by a second person before it
becomes part of main. In the repository settings under
“Branches”, you can even protect main, so that changes can
only get there through a pull request.
Review a pull request
Now we switch roles. Our partner has opened a pull request in our repository, and it’s our job to review it.
We go to our own my-git-repo-<name> repository,
click on the tab “Pull requests” and open the pull request from our
partner. Then we click on “Files changed” to see the changes.
When we hover over a line of the changes, a small +
button appears next to the line number. Clicking it opens a text field
to comment on this particular line. Let’s ask for a small change, for
example:
We click “Start review”. We could add more comments on other lines in the same way. When we’re done, we click “Finish review” at the top of the changes, choose “Request changes”, write a short summary and submit the review.
Reviews
Reviewing changes before they are merged is a common practice in software development (code review), but it is just as useful for documentation, metadata or data files: a second pair of eyes catches mistakes, and the discussion is saved together with the change. Comments on individual lines keep separate topics in separate discussions.
Update a pull request
Back in our role as author, we see the review on our pull request in our partner’s repository. To update a pull request, we don’t need to create a new one: we simply add a new commit to the same branch.
In our fork, we use the branch selector above the list of files to
switch to the branch add-contributors. We click on
CONTRIBUTORS.md and then on the pencil icon (“Edit file”),
and change our line, for example:
As commit message, we enter “Add link to Codeberg profile”. This
time, we keep “Commit directly to the add-contributors
branch” selected and click “Commit changes”.
If we reload the pull request page, we see the new commit in the conversation. We can answer the review comment, for example with “Done!”, and mark the conversation as resolved.
Merge the pull request
Switching roles a last time, we look at the updated pull request in our own repository. If we’re happy with the changes, we can approve them: click “Finish review” in the “Files changed” tab, choose “Approve” and submit.
At the bottom of the “Conversation” tab, Codeberg tells us whether the pull request can be merged without conflicts. We click the merge button (“Create merge commit”) and confirm.
Codeberg now creates a merge commit in our main branch.
If we open the linked issue, we see that it has been closed
automatically, with a note in its history pointing to the pull request
that closed it.
Finally, we update the repository on our own computer, so that it
contains the merged changes too. This is the same git pull
as in the episode Sharing your work:
OUTPUT
...
Fast-forward
 CONTRIBUTORS.md | 6 ++++++
 1 file changed, 6 insertions(+)
create mode 100644 CONTRIBUTORS.mdChallenge: The whole workflow
Draw the complete workflow of this episode on a sheet of paper or a
whiteboard, together with your partner. Include your partner’s
repository, your fork, the branch add-contributors, the
pull request and your own repository on your computer, and show with
arrows where the fork, the commits, the pull request, the merge and the
final git pull happen.
Challenge: When to use what?
You are working on a data project with two colleagues and want to suggest a change. In which of these situations would you use
- a commit directly to
main, - an issue,
- a pull request?
- You found a typo in the README of a public dataset from another institute.
- You noticed that some values in a data file look wrong, but you don’t know how to fix them.
- You want to add a new section to your team’s documentation, and the team has agreed to review all changes.
- You are the only person working on your own repository and want to save your progress.
- A pull request from a fork (or an issue, if you don’t want to make the change yourself): you don’t have write access to the repository.
- An issue: describe the problem, so that the people who know the data can investigate and fix it.
- A pull request from a branch in the shared repository, so that your colleagues can review it.
- A commit directly to
mainis fine – although a branch and a pull request can still help you to keep track of bigger changes.
- A pull request (on GitLab: merge request) suggests changes from one branch to another, often from a fork to the original repository
- Work on a new branch for each contribution
-
Closes #<number>in a pull request description closes the issue when the pull request is merged - Reviewers can comment on individual lines and approve or request changes
- New commits on the branch update the pull request